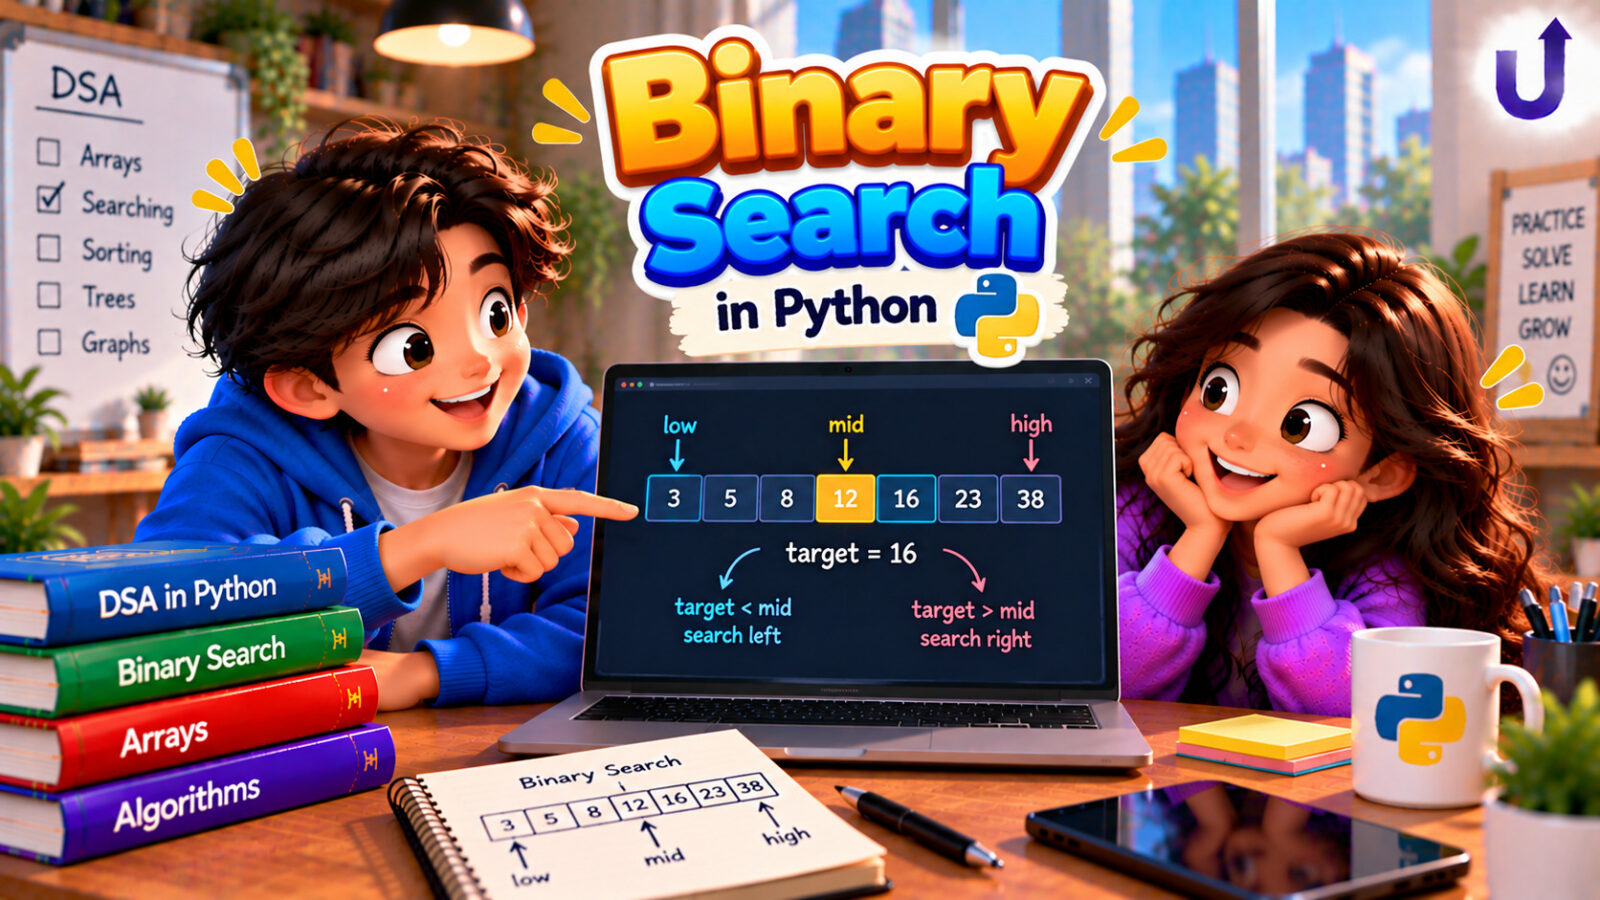
Binary search finds a value in a sorted list by cutting the search area in half at every step. Look at the middle item. If it is too small, the answer must be in the right half. If it is too big, in the left half. Repeat until you find it or nothing is left. It is the same trick as guessing a number between 1 and 100: guess 50, and you learn which half to keep.
This guide shows the standard version, then the three variations that appear again and again in interviews: finding the first or last occurrence, finding an insertion position, and searching on the answer instead of on a list. It also covers Python’s bisect module, which does much of this for you. All the output shown is real.
In this guide
The short version
- Needs sorted data. It keeps two ends,
loandhi, and checks the middle. - Time is
O(log n): a million items need about 20 steps. - For duplicates, do not stop at the first match. Keep searching left (first) or right (last).
- Insertion position is
bisect_left. Use it for “where would this go”. - Any question shaped “smallest value that works” can be binary searched, even when there is no list.
The classic version
Keep lo and hi as the ends of the area still in play. Check mid. If it matches, return it. Otherwise move one end past mid. When lo passes hi, the value is not there:
def binary_search(items, target):
    lo, hi = 0, len(items) - 1
    while lo <= hi:
        mid = (lo + hi) // 2
        if items[mid] == target:
            return mid
        if items[mid] < target:
            lo = mid + 1
        else:
            hi = mid - 1
    return -1

nums = [2, 5, 8, 12, 16, 23, 38, 56, 72, 91]
print(binary_search(nums, 23))
print(binary_search(nums, 91))
print(binary_search(nums, 7))
Output
5
9
-1
Here is what happens step by step when searching for 23. The area shrinks from 10 items, to 5, to 2:
nums = [2, 5, 8, 12, 16, 23, 38, 56, 72, 91]
target = 23
lo, hi = 0, len(nums) - 1
while lo <= hi:
    mid = (lo + hi) // 2
    print(f"lo={lo} hi={hi} mid={mid} value={nums[mid]}")
    if nums[mid] == target:
        print("found at index", mid)
        break
    if nums[mid] < target:
        lo = mid + 1
    else:
        hi = mid - 1
Output
lo=0 hi=9 mid=4 value=16
lo=5 hi=9 mid=7 value=56
lo=5 hi=6 mid=5 value=23
found at index 5
Note the + 1 and - 1. Since mid has already been checked, it must be excluded from the next round. Otherwise the loop can get stuck forever.
How fast is it?
Each step halves the search area, so the number of steps is about the number of times you can halve n until you reach 1. That is log2(n). We count steps here, not seconds, so the answer is the same on every computer. Linear search may need to look at every item:
def steps_needed(items, target):
    lo, hi, steps = 0, len(items) - 1, 0
    while lo <= hi:
        steps += 1
        mid = (lo + hi) // 2
        if items[mid] == target:
            return steps
        if items[mid] < target:
            lo = mid + 1
        else:
            hi = mid - 1
    return steps

for n in [1_000, 1_000_000]:
    items = list(range(n))
    print(n, "items: linear search up to", n, "steps, binary search", steps_needed(items, n - 1), "steps")
Output
1000 items: linear search up to 1000 steps, binary search 10 steps
1000000 items: linear search up to 1000000 steps, binary search 20 steps
Doubling the list adds only one more step. That is what O(log n) means. (See Big O Notation in Python.) The catch is the input must be sorted. If it is not:
def binary_search(items, target):
    lo, hi = 0, len(items) - 1
    while lo <= hi:
        mid = (lo + hi) // 2
        if items[mid] == target:
            return mid
        if items[mid] < target:
            lo = mid + 1
        else:
            hi = mid - 1
    return -1

items = [5, 1, 4, 2, 3]
print(1 in items)
print(binary_search(items, 1))
print(binary_search(sorted(items), 1))
Output
True
-1
0
The first check jumped over the 1 and then discarded the half that contained it. Binary search on unsorted data gives wrong answers without any error, so sort first (sorted(items)) if you are not sure. Sorting costs O(n log n), which only pays off if you search many times.
Variation 1: first and last occurrence
The classic version returns some matching index. With duplicates, which one you get is arbitrary. To find the first occurrence, do not stop at a match. Remember it, and then keep looking on the left half in case there is an earlier one. For the last occurrence, keep looking right:
def first_index(items, target):
    lo, hi, ans = 0, len(items) - 1, -1
    while lo <= hi:
        mid = (lo + hi) // 2
        if items[mid] == target:
            ans = mid
            hi = mid - 1              # found one, but look further left
        elif items[mid] < target:
            lo = mid + 1
        else:
            hi = mid - 1
    return ans

def last_index(items, target):
    lo, hi, ans = 0, len(items) - 1, -1
    while lo <= hi:
        mid = (lo + hi) // 2
        if items[mid] == target:
            ans = mid
            lo = mid + 1              # found one, but look further right
        elif items[mid] < target:
            lo = mid + 1
        else:
            hi = mid - 1
    return ans

items = [1, 2, 2, 2, 2, 3, 5]
print(first_index(items, 2), last_index(items, 2))
print(last_index(items, 2) - first_index(items, 2) + 1)
print(first_index(items, 4), last_index(items, 4))
Output
1 4
4
-1 -1
With both, the number of copies is last - first + 1, in O(log n), instead of scanning the whole list to count. This pattern, “found it, but keep going”, is the heart of most binary search variations.
Variation 2: insertion position
“Where would 4 go in [1, 3, 5, 7] so the list stays sorted?” This is called the lower bound: the index of the first item that is greater than or equal to the target. This version uses a half-open range (hi starts at len(items) and the loop is lo < hi), which makes it easy to get right:
def lower_bound(items, target):
    """Index of the first item >= target (len(items) if there is none)."""
    lo, hi = 0, len(items)
    while lo < hi:
        mid = (lo + hi) // 2
        if items[mid] < target:
            lo = mid + 1
        else:
            hi = mid
    return lo

items = [1, 3, 5, 7]
for target in [0, 3, 4, 7, 8]:
    print(target, "->", lower_bound(items, target))
Output
0 -> 0
3 -> 1
4 -> 2
7 -> 3
8 -> 4
If the target exists, the result is its (first) index. If not, it is where it should be inserted. A result equal to len(items) means “larger than everything”. A search that returns “found or not” is then just i < len(items) and items[i] == target.
The bisect module
Python already ships this. bisect_left is the lower bound above, and bisect_right gives the position just after any equal items. Together they count occurrences. insort inserts while keeping the list sorted. A neat everyday use is looking up a grade or a tax slab from a list of cut-offs:
import bisect

items = [1, 2, 2, 2, 2, 3, 5]
left = bisect.bisect_left(items, 2)
right = bisect.bisect_right(items, 2)
print(left, right, right - left)
print(bisect.bisect_left(items, 4))

scores = [60, 70, 80, 90]
grades = "FDCBA"
print([grades[bisect.bisect(scores, s)] for s in [55, 60, 75, 89, 90, 100]])

bisect.insort(items, 4)
print(items)
Output
1 5 4
6
['F', 'D', 'C', 'B', 'A', 'A']
[1, 2, 2, 2, 2, 3, 4, 5]
In interviews you are usually expected to write the loop yourself, but in real code, use bisect. (It also appears in Binary Search Tree in Python From Scratch, as the sorted-list alternative.) Note that insort is still O(n), because items shift to make room.
Variation 3: search on the answer
This is the most powerful idea. You do not need a list at all. You need a range of possible answers, and a yes-or-no test that flips exactly once from “no” to “yes” as the answer grows. Then you can binary search the range.
Example. Koko has piles of bananas and h hours. Each hour she picks one pile and eats up to k bananas from it. What is the smallest k that lets her finish in time? If speed 4 is enough, then 5, 6 and every faster speed are enough too, so the test “can she finish at speed k?” goes no, no, no, yes, yes, yes. We look for the first “yes”:
def min_speed(piles, hours):
    lo, hi = 1, max(piles)
    while lo < hi:
        mid = (lo + hi) // 2
        needed = sum((p + mid - 1) // mid for p in piles)     # hours at speed mid
        if needed <= hours:
            hi = mid              # mid works, try slower
        else:
            lo = mid + 1          # too slow
    return lo

print(min_speed([3, 6, 7, 11], 8))
print(min_speed([30, 11, 23, 4, 20], 5))
print(min_speed([30, 11, 23, 4, 20], 6))
Output
4
30
23
The speed can be anything from 1 to the largest pile (max(piles)), so at most about 30 tests are needed even for enormous piles, instead of trying every speed. The template is always the same: if the middle value works, keep it as a possible answer and search lower (hi = mid). If not, search higher (lo = mid + 1).
The mirror case is “the largest value that works”. The integer square root of n is the largest x with x * x <= n. Here mid is rounded up. Otherwise, when lo and hi are next to each other, lo = mid would never move:
def isqrt(n):
    lo, hi = 0, n
    while lo < hi:
        mid = (lo + hi + 1) // 2      # round up, or lo = mid could loop forever
        if mid * mid <= n:
            lo = mid
        else:
            hi = mid - 1
    return lo

print(isqrt(16), isqrt(17), isqrt(99), isqrt(0))
Output
4 4 9 0The same thinking solves “ship packages within D days”, “split an array into k parts with the smallest largest sum”, and “the smallest number that satisfies X”.
Bonus: a rotated sorted list
Take a sorted list and rotate it: [0, 1, 2, 4, 5, 6, 7] becomes [4, 5, 6, 7, 0, 1, 2]. It is no longer sorted, but at least one half of any split is. At each step, work out which half is sorted, and check whether the target lies inside it:
def search_rotated(nums, target):
    lo, hi = 0, len(nums) - 1
    while lo <= hi:
        mid = (lo + hi) // 2
        if nums[mid] == target:
            return mid
        if nums[lo] <= nums[mid]:                 # the left half is sorted
            if nums[lo] <= target < nums[mid]:
                hi = mid - 1
            else:
                lo = mid + 1
        else:                                     # the right half is sorted
            if nums[mid] < target <= nums[hi]:
                lo = mid + 1
            else:
                hi = mid - 1
    return -1

nums = [4, 5, 6, 7, 0, 1, 2]
print(search_rotated(nums, 0), search_rotated(nums, 5), search_rotated(nums, 3))
Output
4 1 -1Still O(log n). This one is asked so often because it checks whether you truly understand what binary search relies on.
Complexity
| Version | Time | Extra space |
|---|---|---|
| Classic search | O(log n) | O(1) |
| First or last occurrence | O(log n) | O(1) |
| Insertion position, bisect_left | O(log n) | O(1) |
| Search on the answer | O(log(range) x cost of one test) | O(1) |
| Linear search, for comparison | O(n) | O(1) |
A recursive version works too, but uses O(log n) stack space, so the loop is preferred.
Common mistakes
- Using it on unsorted data. The result is silently wrong.
- Infinite loops. Writing
lo = midinstead oflo = mid + 1can stall. If you must keepmid, roundmidup or down as needed, like inisqrt. - Mixing two styles.
lo <= higoes withhi = len - 1andhi = mid - 1.lo < higoes withhi = len(orhi = mid). Pick one and stay with it. - Returning the first match when you need the first occurrence. With duplicates, keep going after a match.
- Off-by-one at the ends. Test empty lists, one item, the first item, the last item and missing items on both sides.
- Sorting on every search. That makes each search
O(n log n). Sort once, search many times.
Try it yourself
Work out each answer first, then open the solution.
1. How many values in the sorted list [1, 3, 3, 5, 7, 9, 11] lie between 3 and 9, inclusive? Use bisect.
Show solution
import bisect

def count_in_range(items, low, high):
    return bisect.bisect_right(items, high) - bisect.bisect_left(items, low)

print(count_in_range([1, 3, 3, 5, 7, 9, 11], 3, 9))
Output
5bisect_left(low) is the first index that is at least 3. bisect_right(high) is the index just after the last 9. Their difference is the count: 3, 3, 5, 7, 9.
2. A list rises and then falls, like [1, 3, 6, 9, 7, 4, 2]. Find the index of the peak in O(log n).
Show solution
def peak_index(nums):
    lo, hi = 0, len(nums) - 1
    while lo < hi:
        mid = (lo + hi) // 2
        if nums[mid] < nums[mid + 1]:
            lo = mid + 1              # still going up
        else:
            hi = mid                  # going down: the peak is here or left
    return lo

print(peak_index([1, 3, 6, 9, 7, 4, 2]))
Output
3Compare mid with its right neighbour. If the list is still rising, the peak is to the right. Otherwise it is here or to the left. The test flips once, so binary search applies.
3. Given [1, 3, 5, 6], where would 5, 2 and 7 be inserted?
Show solution
import bisect

def insert_position(items, target):
    return bisect.bisect_left(items, target)

print(insert_position([1, 3, 5, 6], 5), insert_position([1, 3, 5, 6], 2), insert_position([1, 3, 5, 6], 7))
Output
2 1 4An existing value returns its own index (2), 2 goes between 1 and 3 (index 1), and 7 goes at the end (index 4).
4. Why does the classic search use mid + 1 and mid - 1 instead of just mid?
Show answer
mid has already been checked and was not the answer, so it must be excluded. If you keep it in the range, the area might stop shrinking and the loop can run forever.
Run these in our free Python compiler.
Frequently asked questions
What is binary search in Python?
It is an algorithm that finds a value in a sorted list by repeatedly halving the search area. Python has no built-in function called binary search, but the bisect module provides the same operations.
What is the time complexity of binary search?
O(log n). Each step halves the remaining items, so a million items need about 20 steps and a billion need about 30.
Does binary search work on unsorted data?
No. It relies on the order to decide which half to discard. On unsorted data it can miss values that are in the list, with no error message. Sort the data first.
How do I find the first or last occurrence with duplicates?
When you find a match, remember the index and keep searching: to the left for the first occurrence, to the right for the last. Or use bisect_left and bisect_right.
What is the difference between bisect_left and bisect_right?
For a value that is already in the list, bisect_left returns the index of its first copy, and bisect_right returns the index just after its last copy. For a missing value both return the same position.
What does it mean to binary search on the answer?
It means the values you search are possible answers, not items in a list. If a yes-or-no test changes only once as the value grows, you can binary search for the smallest value that passes, such as the slowest eating speed that still finishes in time.
Related reading
- Big O Notation Explained With Python Examples – why halving is so powerful.
- Binary Search Tree in Python From Scratch – the same idea in a tree.
- Sorting Algorithms in Python: Bubble to Merge – how the sorted order is produced.
- 10 Coding Interview Patterns in Python – where binary search fits among the patterns.
Run this code in your browser
The free Upskly compiler runs Python with nothing to install. Paste the example, change it and see what happens.
Stuck on a traceback?
AI Assist works inside the Python notebook, so you can ask about an error or a concept without leaving the cell.
Test yourself
Timed questions on Sorting and Binary Search, with an explanation for every answer.