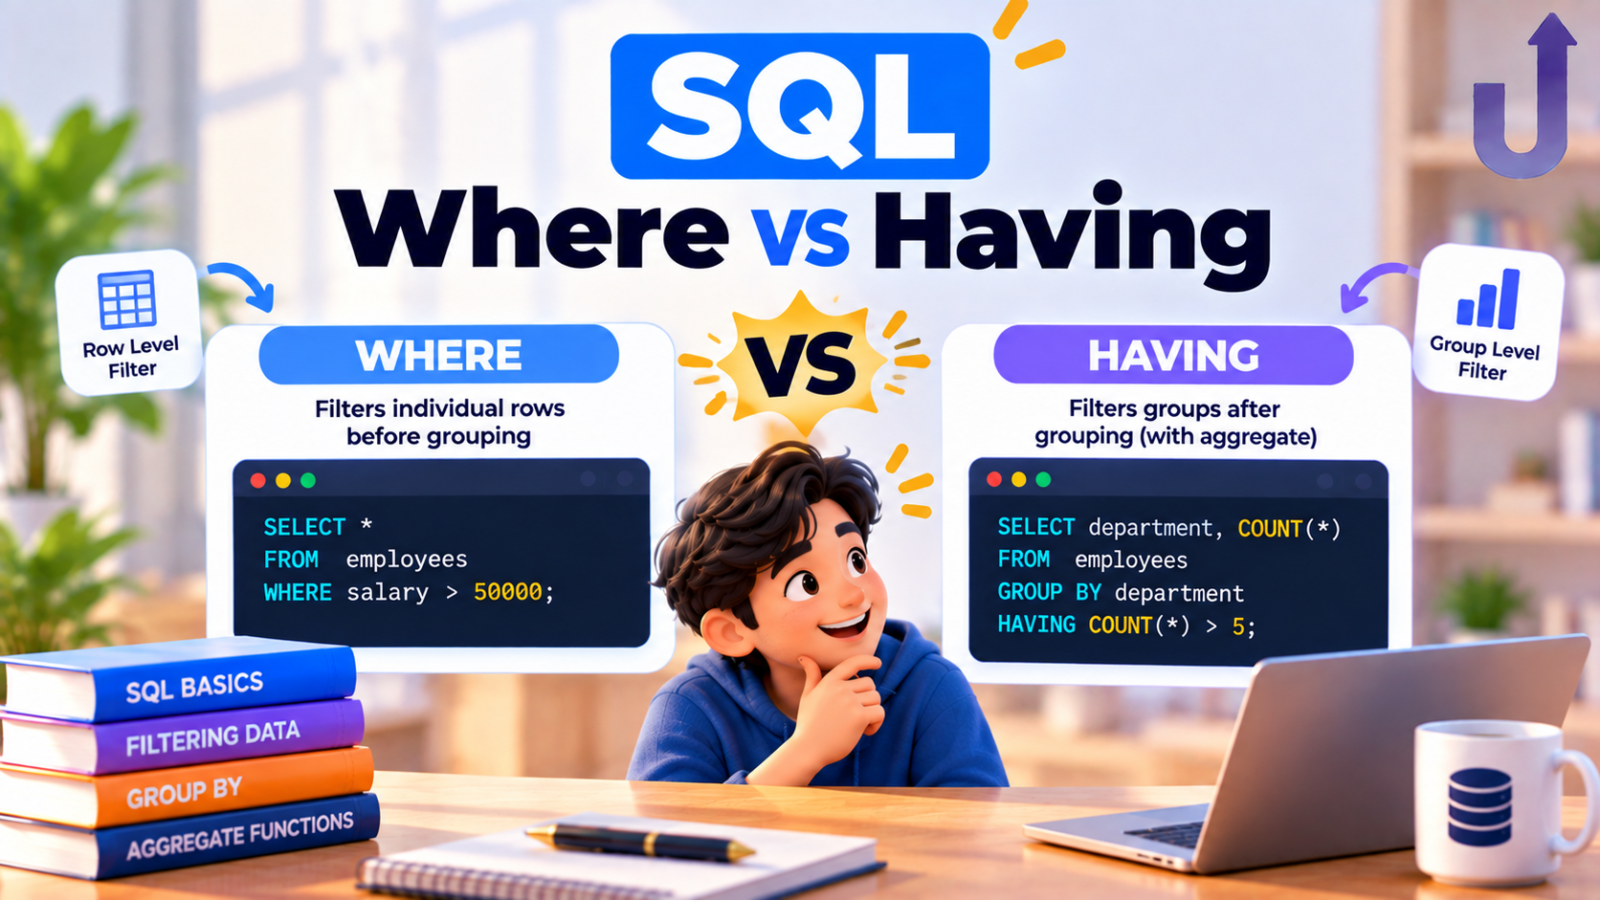
The difference between WHERE and HAVING in SQL is timing. WHERE filters individual rows before they are grouped. HAVING filters whole groups after GROUP BY has run.
That is why WHERE cannot use aggregate functions like SUM() or COUNT(), while HAVING can. The rest of this guide shows it with one small table and real outputs.
In this guide
The short version
- WHERE – filters rows. Runs before
GROUP BY. Cannot use aggregates. - HAVING – filters groups. Runs after
GROUP BY. Can use aggregates likeSUM()andCOUNT().
The table we will use
A small orders table. Customer 1 has two completed and two cancelled orders, which will matter in a moment.
| order_id | customer_id | amount | status |
|---|---|---|---|
| 101 | 1 | 500 | completed |
| 102 | 1 | 300 | completed |
| 103 | 1 | 200 | cancelled |
| 104 | 1 | 400 | cancelled |
| 105 | 2 | 700 | completed |
| 106 | 2 | 250 | completed |
| 107 | 2 | 150 | completed |
| 108 | 2 | 600 | completed |
| 109 | 3 | 900 | completed |
Want to run this yourself? Copy the setup SQL
CREATE TABLE orders (order_id INT, customer_id INT, amount INT, status VARCHAR(20));
INSERT INTO orders VALUES
  (101, 1, 500, 'completed'),
  (102, 1, 300, 'completed'),
  (103, 1, 200, 'cancelled'),
  (104, 1, 400, 'cancelled'),
  (105, 2, 700, 'completed'),
  (106, 2, 250, 'completed'),
  (107, 2, 150, 'completed'),
  (108, 2, 600, 'completed'),
  (109, 3, 900, 'completed');
Works in MySQL, PostgreSQL and SQLite. Paste it into any of them, then run the queries from this guide.
What is the WHERE clause?
WHERE looks at one row at a time and keeps it only if the condition is true. Here we keep just the completed orders:
SELECT order_id, customer_id, amount
FROM orders
WHERE status = 'completed';| order_id | customer_id | amount |
|---|---|---|
| 101 | 1 | 500 |
| 102 | 1 | 300 |
| 105 | 2 | 700 |
| 106 | 2 | 250 |
| 107 | 2 | 150 |
| 108 | 2 | 600 |
| 109 | 3 | 900 |
Nine rows went in, seven came out. Nothing has been grouped or added up yet. WHERE works on the raw rows.
What is the HAVING clause?
Suppose you want customers whose orders add up to more than 1000. First, see the total per customer using GROUP BY:
SELECT customer_id, SUM(amount) AS total
FROM orders
GROUP BY customer_id;| customer_id | total |
|---|---|
| 1 | 1400 |
| 2 | 1700 |
| 3 | 900 |
Now the question is about the total, which only exists after grouping. A row-level WHERE cannot see it, so we use HAVING:
SELECT customer_id, SUM(amount) AS total
FROM orders
GROUP BY customer_id
HAVING SUM(amount) > 1000;| customer_id | total |
|---|---|
| 1 | 1400 |
| 2 | 1700 |
Customer 3 (total 900) is filtered out. HAVING looked at each group’s total and kept only the groups that passed.
The order SQL runs your query in
You write SELECT first, but the database does not run it first. Logically, it works through the clauses in this order:
- FROM (and any JOINs) – decide which table the rows come from
- WHERE – throw away individual rows
- GROUP BY – bundle the remaining rows into groups
- HAVING – throw away whole groups
- SELECT – work out the columns you asked for
- ORDER BY – sort the result
This one list explains almost every WHERE-vs-HAVING question. When WHERE runs, groups do not exist yet, so there is no total to compare. By the time HAVING runs, they do. It also explains why, in standard SQL and in MySQL, PostgreSQL and SQL Server, you cannot use a column alias from SELECT inside WHERE: SELECT has not run yet. (SQLite is more lenient and allows it, but do not rely on that.)
Using WHERE and HAVING together
You can, and often should, use both. Let us find customers whose completed orders add up to more than 1000:
SELECT customer_id, SUM(amount) AS total
FROM orders
WHERE status = 'completed'
GROUP BY customer_id
HAVING SUM(amount) > 1000;| customer_id | total |
|---|---|
| 2 | 1700 |
Step by step:
WHEREkeeps the 7 completed orders and drops the 2 cancelled ones.GROUP BYadds them up per customer:
| customer_id | total |
|---|---|
| 1 | 800 |
| 2 | 1700 |
| 3 | 900 |
HAVING SUM(amount) > 1000keeps only customer 2 (1700).
Compare this with the earlier HAVING-only query, which returned customers 1 and 2. Customer 1 only passed because their two cancelled orders (600) were counted. Both queries run without any error, but they answer different business questions. Deciding whether cancelled orders should count is the real work, and WHERE is where you make that decision.
Common mistakes
Mistake 1: using an aggregate in WHERE
SELECT customer_id, SUM(amount) AS total
FROM orders
WHERE SUM(amount) > 1000   -- error
GROUP BY customer_id;
This fails. MySQL reports Invalid use of group function and PostgreSQL reports aggregate functions are not allowed in WHERE. At the WHERE step there are no groups yet, so SUM(amount) has nothing to add up. Move that condition to HAVING.
Mistake 2: putting a plain row filter in HAVING
When a condition is about a single column, and that column is in your GROUP BY, both of these give the same answer:
SELECT customer_id, SUM(amount) AS total
FROM orders
WHERE customer_id = 2
GROUP BY customer_id;
SELECT customer_id, SUM(amount) AS total
FROM orders
GROUP BY customer_id
HAVING customer_id = 2;| customer_id | total |
|---|---|
| 2 | 1700 |
But the WHERE version is better. It throws away the other customers before grouping, so the database has less to group. It is also clearer to read. Rule of thumb: if it can go in WHERE, put it in WHERE. Save HAVING for conditions on aggregates.
WHERE vs HAVING at a glance
| WHERE | HAVING | |
|---|---|---|
| Filters | Individual rows | Groups of rows |
| Runs | Before GROUP BY | After GROUP BY |
| Can use SUM(), COUNT(), AVG()? | No | Yes |
| Can use plain columns? | Yes | Only columns that are grouped (or aggregates) |
| Typical example | WHERE status = 'completed' | HAVING SUM(amount) > 1000 |
Try it yourself
Use the orders table above. Work out the answer first, then open the solution.
1. Which customers have at least 3 completed orders?
Show solution
SELECT customer_id, COUNT(*) AS completed_orders
FROM orders
WHERE status = 'completed'
GROUP BY customer_id
HAVING COUNT(*) >= 3;| customer_id | completed_orders |
|---|---|
| 2 | 4 |
2. Which customers have more than one cancelled order?
Show solution
SELECT customer_id, COUNT(*) AS cancelled_orders
FROM orders
WHERE status = 'cancelled'
GROUP BY customer_id
HAVING COUNT(*) > 1;| customer_id | cancelled_orders |
|---|---|
| 1 | 2 |
Both need WHERE to pick the status first and HAVING to test the count. When you are ready for more, run them in our free SQL compiler.
Frequently asked questions
Can I use HAVING without GROUP BY?
In most databases, yes. The whole table is treated as one group, so the query returns at most one row. It is uncommon in practice. Almost every real use of HAVING comes with GROUP BY.
Can I use WHERE and HAVING in the same query?
Yes. WHERE filters rows first, then GROUP BY groups what is left, then HAVING filters the groups. See the completed-orders example above.
Why can’t I use SUM() in a WHERE clause?
Because WHERE runs before grouping. At that point the database is looking at single rows and no group total exists yet. Use HAVING for conditions on aggregates.
Which is faster, WHERE or HAVING?
When a condition can go in either, WHERE is usually faster because it removes rows before grouping, so there is less data to group. Put row-level conditions in WHERE and aggregate conditions in HAVING.
Can HAVING use a column alias from SELECT?
It depends on the database. MySQL allows it, while PostgreSQL and SQL Server do not. To stay portable, repeat the expression, for example HAVING SUM(amount) > 1000, instead of using the alias total.
Related reading
- SQL Joins Explained – INNER, LEFT, RIGHT and FULL with examples.
- SQL Window Functions Explained – calculate across rows without collapsing them like GROUP BY does.
- NULL in SQL – why some filters quietly drop rows.
Test it under a timer
WHERE vs HAVING is a favourite interview topic. Try timed SQL questions on grouping and filtering.
Want a structured path instead?
Structured SQL courses – built for real data roles.